Extend Amazon Bedrock Guardrails to Tool Interactions Using the Strands Agents SDK
August 27, 2026 · AWS Security · Severity: CRITICAL
Amazon Bedrock Guardrails can now be extended to manage tool interactions through the Strands Agents SDK, enhancing safety for agentic AI workflows. This integration allows developers to define and enforce guardrails directly on tool calls made by AI agents, reducing risky or unintended behaviors. The approach leverages existing Bedrock Guardrails policies to filter both inputs and outputs during tool use, ensuring consistent security across the agent lifecycle. By incorporating these controls, organizations can deploy generative AI applications with improved trust and compliance.
If you’re running AI agents in production, Amazon Bedrock Guardrails protects the model boundary. But your agents also invoke tools, fetch external data, and communicate with other systems. That data flows outside the model boundary, where model-level guardrails can’t reach.
You can extend guardrail coverage to those interactions using three validation checkpoints built with the Strands Agents SDK lifecycle hooks and Amazon Bedrock guardrails. You implement each checkpoint using a Strands life-cycle hook, which validates data at a critical trust boundary without changing your existing tools or agent logic.
Agents can communicate with other systems through the Model Context Protocol (MCP), a standard for connecting AI systems to data sources and tools. You will learn how to implement three validation checkpoints, scope different guardrails to specific tools, and scale them to other agents.
Extending guardrails beyond the model boundary
Amazon Bedrock Guardrails provides protection at the model boundary. Every model invocation is checked: the input prompt is validated before inference, and the model response is validated after inference. You can enforce guardrail use at the account level using AWS Identity and Access Management (IAM) policies, making guardrails mandatory for model calls across your account. You can further refine this by using Amazon Bedrock Guardrails input tagging to mark specific portions of the prompt for evaluation, so trusted content like system prompts can be skipped.
Guardrails cover what the model sees, but agents do more than call models. They invoke tools, pull data from external sources, communicate with MCP servers, and return results to users. These interactions happen outside the model boundary by design, because model-level guardrails focus on the prompts and responses the model itself handles. Adding validation at the tool boundary complements, rather than replaces, that model-level protection.
Model-level guardrails alone leave you exposed in four ways:
- Tool parameters pass through unchecked. The model decides which tool to use and what parameters to pass. The agent then calls the tool with those parameters. No validation sits between the model’s decision and the tool’s execution. If the parameters inadvertently contain personally identifiable information (PII) or policy-violating content, the tool runs with that content.
- External data enters without validation. Agents consume data from tool responses, MCP server outputs, and API calls. Without validation at the tool boundary, content from external sources can influence the agent’s behavior before model-level guardrails have a chance to evaluate it.
- Misleading content can affect reasoning. An agent that retrieves inaccurate or misleading content from an external source might treat it as authoritative, producing skewed recommendations in lending, healthcare, or legal advice.
- Multi-agent systems can spread bad data downstream. In multi-agent systems, a misconfigured or poorly designed upstream component can pass policy-violating content to downstream agents. Model-level guardrails at each agent’s boundary don’t inspect data flowing between agents at the tool layer.
Three validation checkpoints
To close these gaps, add three validation checkpoints at each trust boundary where data crosses into or out of your agent as shown in Figure 1.
- Checkpoint 1: Inbound data validation – Check data before it reaches the model—user input, data from other agents, MCP tool servers, and RAG pipelines. You catch policy-violating or biased content before it enters the model’s context window. In the Strands Agents SDK, you implement this using a
BeforeInvocationEventhook that fires before model inference or tool execution occurs. The hook inspects incoming messages and blocks the request if the content violates policies. The model doesn’t see blocked content. - Checkpoint 2: Tool interaction supervision – Before the agent calls a tool, a
BeforeToolCallEventhook checks the parameters it’s about to pass. This is the gap model-level guardrails don’t cover. The model has already decided what to send, but nothing has verified whether that content is safe to act on. If the hook flags the input, the call is canceled before the real-world action occurs. - Checkpoint 3: Outbound data validation – Validate results before returning them to the user or passing them to downstream systems. You need this most for tools that ingest external content, like a web search tool fetching web pages from sites outside your control. In Strands, an
AfterToolCallEventhook validates the tool’s return value and replaces it with a block message if the content violates policies.
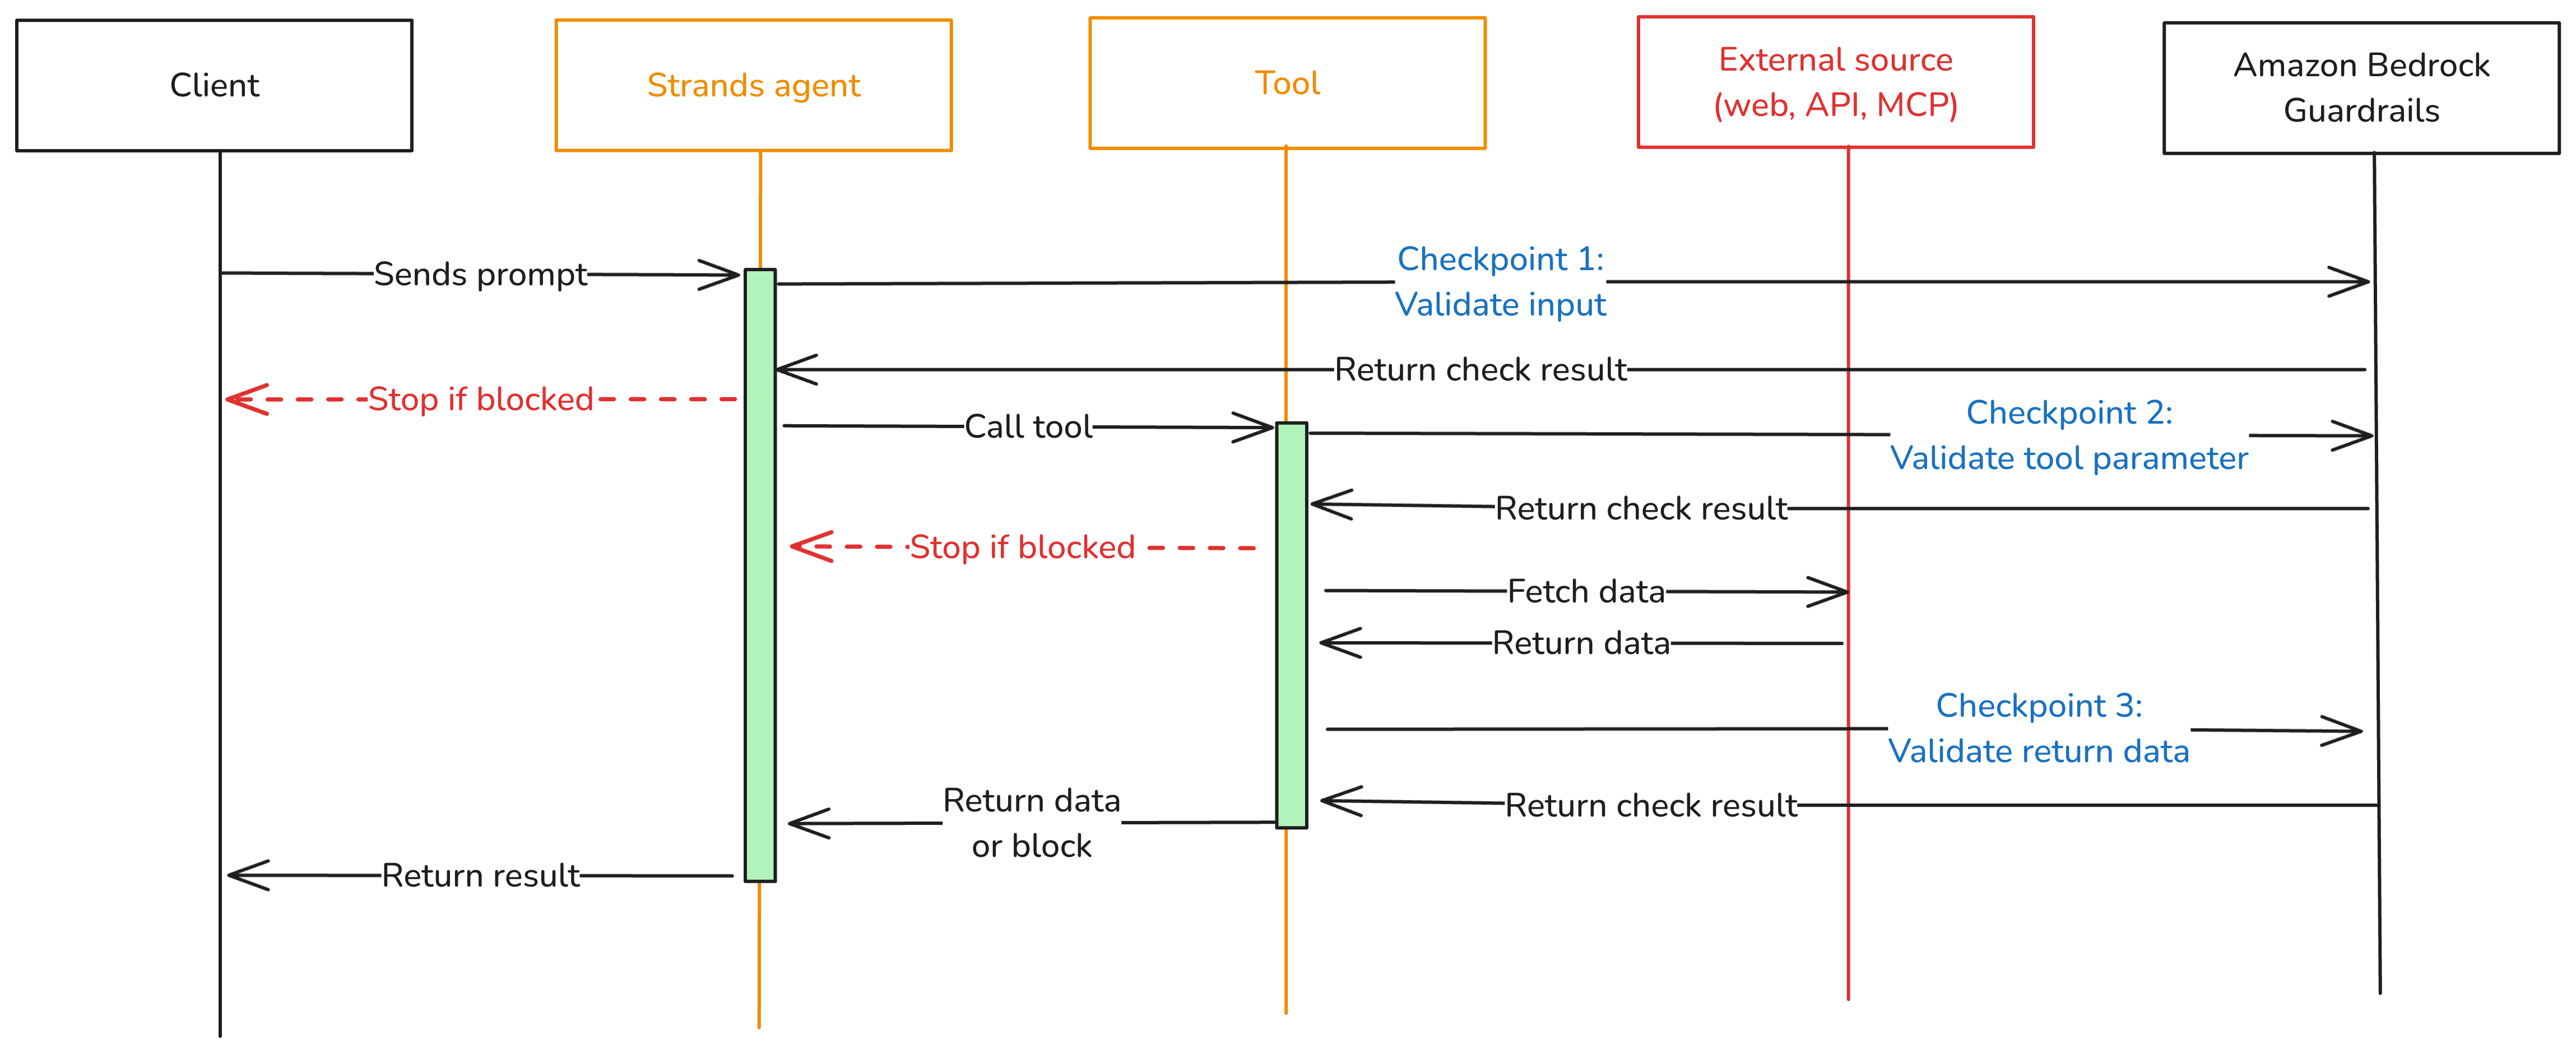
Figure 1: Three validation checkpoints extend Amazon Bedrock Guardrails from the model boundary to the tool boundary.
You can adjust the validation intensity of each checkpoint:
- At Checkpoint 1, use a full Amazon Bedrock guardrail with PII detection, content filtering, and topic enforcement.
- Checkpoint 2 can be lighter. Configure a separate Amazon Bedrock guardrail with rules tailored to the specific tool being called, or run local checks like regex validation or schema enforcement.
- For Checkpoint 3, focus on unwanted content detection for tool outputs that return external data.
Mix fast deterministic checks (regex, schema validation, allowlists) with AI-based guardrail evaluations. This keeps latency low.
Implementation
The implementation uses boto3, the AWS SDK for Python, to call the ApplyGuardrail API. The Strands Agents SDK exposes one life-cycle event per checkpoint. Here’s how to implement each one.
Prerequisites
This post assumes you already have a working Strands agent. Your agent should use least-privilege tool access, scoped system prompts, and validated business logic. If you’re starting from scratch, see Strands Agents SDK: A technical deep dive into agent architectures and observability for a step-by-step walk through of building and deploying a Strands agent with Amazon Bedrock Agent Core.
Before implementing the multi-checkpoint approach, you’ will need:
- An AWS account with access to Amazon Bedrock
- Amazon Bedrock Guardrails configured (see Creating a guardrail)
- Python 3.11 or later installed
- The Strands Agents SDK installed: pip install strands-agents
- AWS credentials configured with permissions for
bedrock:ApplyGuardrailandbedrock:InvokeModel - Your guardrail ID and version from the AWS Management Console for Amazon Bedrock (navigate to Guardrails, select your guardrail, and copy the ID)
Create the guardrail validation hook
The GuardrailHook class is a Strands HookProvider. It registers three callbacks, one for each lifecycle event. When Strands triggers an event, the matching callback runs Key Takeaways